Major Media Outlets Are Talking About This AI
AISQ's Next Level Marketing AI delivers fully automated...
OpenArt has launched OpenArt Arena, a public benchmark designed to help creators and enterprises choose AI image and video models according to the specific work they need to complete.
Instead of producing one overall image score and one overall video score, Arena separates models into professional use cases such as filmmaking, graphic design, e-commerce, motion design, video editing, advertising and lip sync. Outputs are compared blindly by creative professionals and a larger pool of selected “tastemakers,” with results calculated through the Bradley–Terry statistical model.
The first rankings position ByteDance’s Seedance 2.5 as the strongest general video model tested, leading the overall video, film, motion-design and lip-sync categories. Wan 3.0 narrowly ranks first for video editing.
Image results are more divided. GPT Image 2 leads graphic design and image editing, while Seedream 5.0 Pro leads film-oriented imagery, e-commerce and the overall image ranking.
OpenArt’s central argument is that creative AI selection has become a routing problem: the best model depends on the job. However, the article also raises an important question about transparency and independence because OpenArt sells access to many of the models its Arena evaluates.
“Which model I use depends entirely on the work required.”
This creator observation captures the core premise behind Arena: different projects require different model capabilities, and budget also affects the practical decision.
“If you just compete on the overall, some models might not be able to be the best.”
OpenArt argues that general leaderboards can conceal models that perform exceptionally well in particular disciplines or against specific criteria.
“For serious work, the only option is Seedance.”
AI filmmaker Zack London offered an especially strong endorsement of Seedance, describing it as substantially ahead of competing video models.
“Cost and speed are also tradeoffs.”
Creator Kiri Margaros emphasized that ranking quality alone is insufficient. Slow generation, high costs and aggressive moderation can make a highly ranked model impractical.
“The most useful benchmark is the one that resembles the organization’s actual work.”
This is the article’s most important caution: external rankings cannot replace testing against a company’s real production demands.
OpenArt Arena reflects a significant shift in how companies may evaluate creative AI. As models become more specialized, businesses may stop looking for one platform to handle every creative task and instead route different jobs to different models.
For creative and marketing teams, this could mean using GPT Image 2 for graphic design, Seedream 5.0 Pro for e-commerce or film imagery, Seedance 2.5 for cinematic video and lip sync, and Wan 3.0 for certain editing workflows.
The rankings also show why small score differences require careful interpretation. Wan 3.0 technically leads Seedance 2.5 in video editing, but the one-point margin does not establish a meaningful superiority when statistical uncertainty is considered.
For enterprise buyers, model openness also matters. Deployment control, data residency, customization, vendor dependence and total cost cannot be captured by aesthetic rankings alone.
OpenArt’s position as both benchmark provider and commercial platform could make Arena highly actionable: users may be able to identify a model and immediately use it in the same environment. At the same time, that commercial relationship creates a governance concern because the benchmark may influence how customers allocate work and spending inside OpenArt.
Ultimately, Arena’s long-term credibility will depend on greater disclosure. Until OpenArt publishes completed evaluator counts, voting volumes, prompt coverage and stronger reproducibility information, businesses should treat its rankings as a useful model-selection map—not an unquestionable industry verdict.

Gateway to AI Adoption. This is the Future of Marketing.
AISQ's Next Level Marketing AI delivers fully automated...
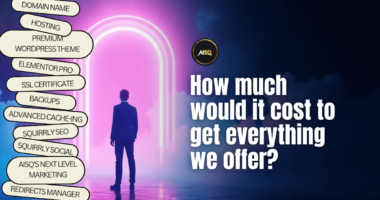
How much would it cost to get everything we offer — i...
14 Days Journey to GEO - Day 4 Welcome to Day 4 of y...